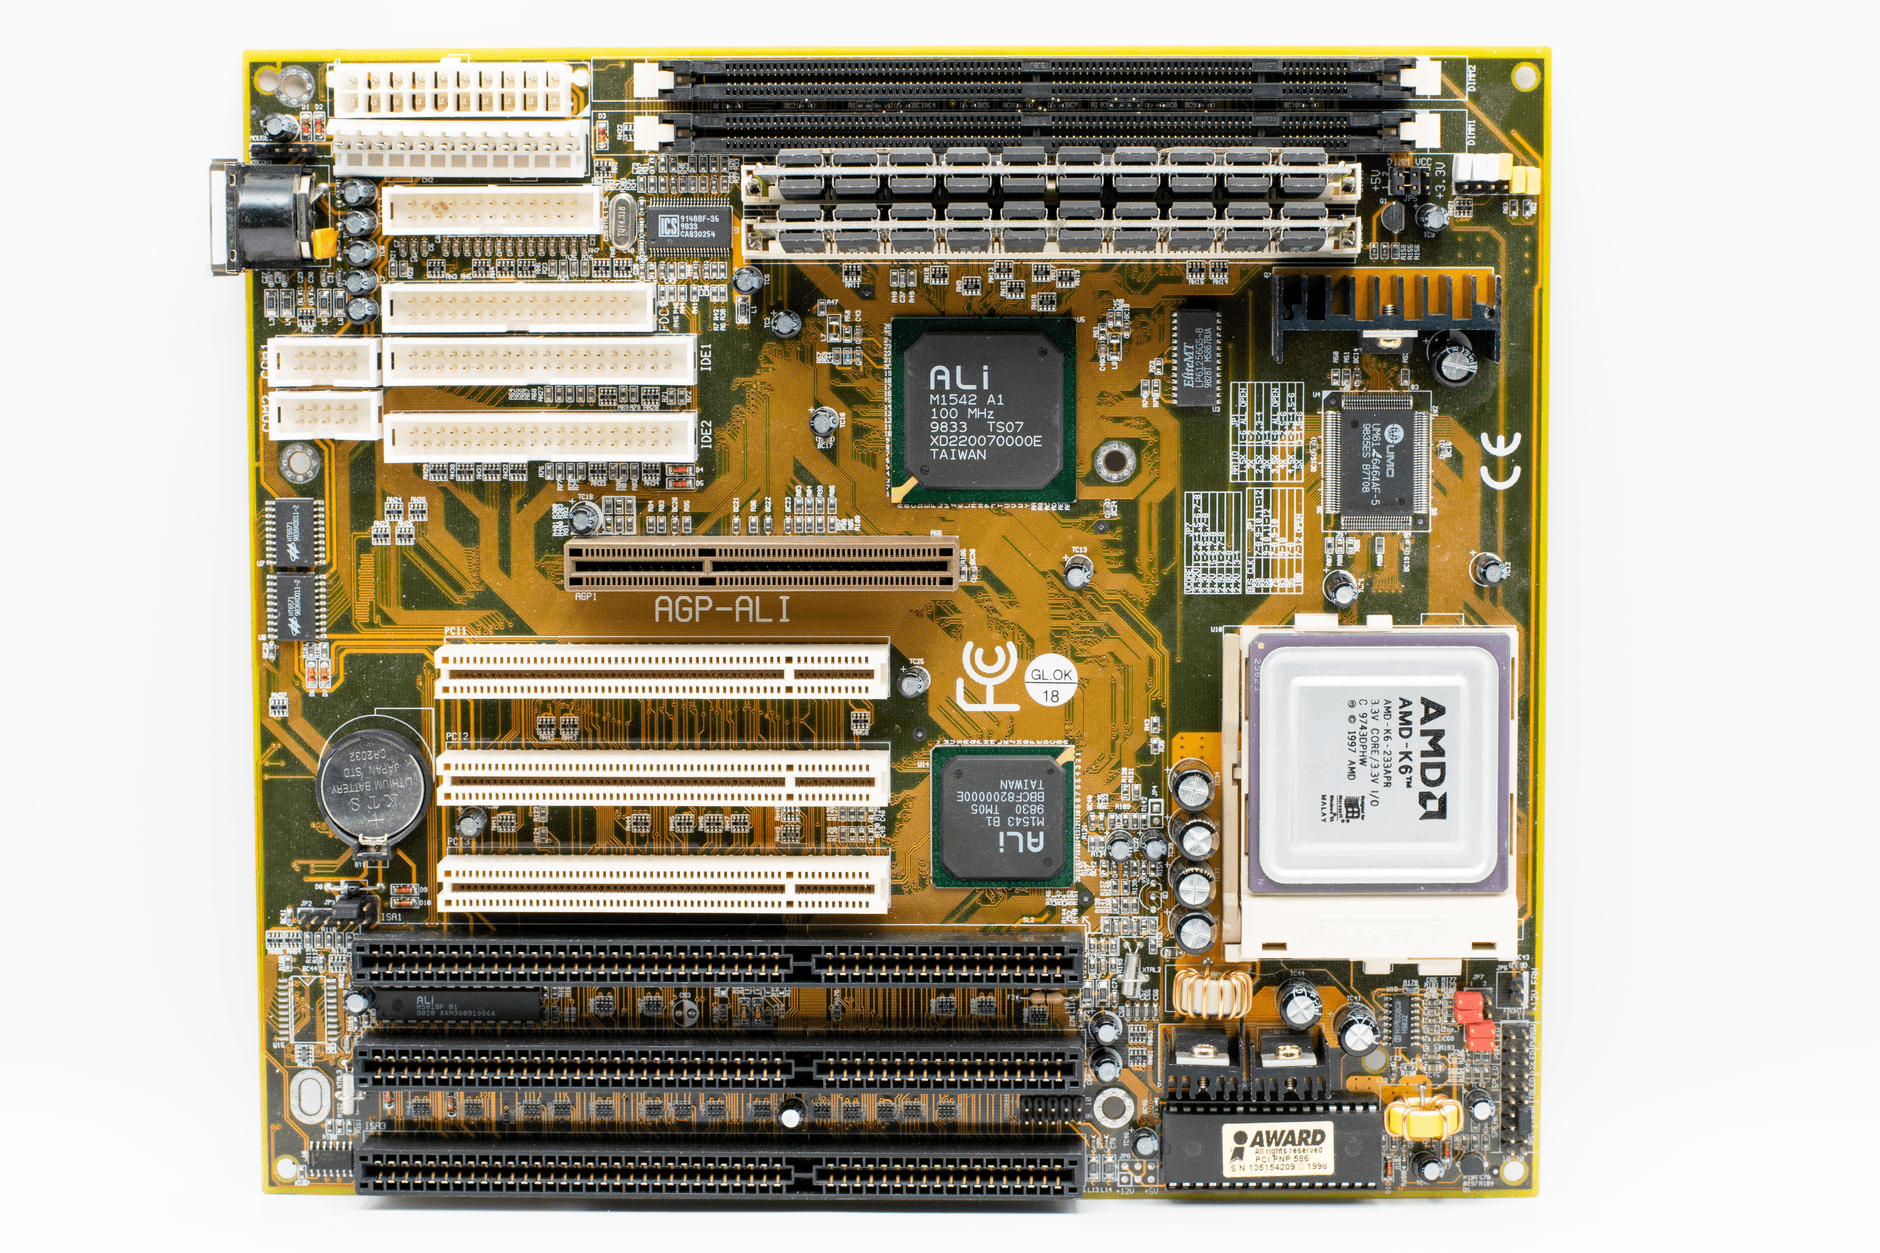
The Art of the Lucky Guess
I’ve spent the last week obsessing over a paradox in the data centers. We have been told for years that the only way to get faster AI is to cram more transistors onto a wafer, yet here we are watching 'speculative decoding' turn that logic on its head. It feels less like a technical optimization and more like a psychological trick played on a computer. Essentially, a tiny, nimble 'draft' model sprints ahead and guesses what the big, heavy model is going to say. If it's right, the big model signs off on it and we save a massive amount of time. If it's wrong, we just throw the guess away and start over.
What fascinates me is the audacity of the gamble. We are purposefully running extra computations—doing more work—in the hopes of doing it faster. It’s the equivalent of a junior assistant drafting an entire email for an executive; most of the time, the assistant gets the gist right, and the executive just hits 'send' instead of typing the whole thing from scratch. On AMD’s MI300X chips, this isn't just a minor tweak. It’s a fundamental decoupling of performance from raw clock speeds. I find myself wondering: if we can guess our way to speed, does the 'brute force' era of silicon design have a shelf life?
Breaking the Nvidia Hegemony with a Shortcut
For the longest time, the narrative was simple: if you aren't on Nvidia's CUDA, you're fighting with one hand tied behind your back. But vLLM’s implementation of speculative decoding on AMD GPUs changes the math of the underdog. The bottleneck for large language models isn't actually math; it's memory bandwidth. The chip spends most of its time waiting for data to move from point A to point B. By using a draft model, we are essentially saturating that idle time with high-probability guesses.
I saw a benchmark recently where this technique yielded a 2x to 3x throughput increase without changing a single physical wire in the GPU. It makes me wonder if the 'hardware moat' we talk about is actually a software-defined mirage. If AMD can use these 'latent speed' tricks to mask their latency gaps, the competitive landscape looks entirely different. We aren't just comparing FLOPS anymore. We are comparing the 'intelligence' of the scheduling software. Is it possible that the next great leap in AI won't come from a fab in Taiwan, but from a more clever way to play this game of Taboo?
Photo by FOX ^.ᆽ.^= ∫ on Pexels
The Efficiency of Being Wrong
There is something deeply human about this system. We are teaching machines to use intuition. When a draft model fails a check, it’s not a system error; it’s just a discarded branch of a conversation. This 'guess-and-verify' loop reminds me of how our own brains likely work—predicting the end of a sentence before our friend finishes speaking. By allowing the machine to be wrong occasionally, we allow it to be significantly faster overall.
I'm curious about the limit of this 'speculative' overhead. Right now, we’re seeing draft models that are 1/10th or 1/100th the size of the target model. What happens when we have hierarchies of five or six models all guessing for each other? We could reach a point where the primary, massive model—the 70B or 400B giant—hardly ever has to 'think' at all. It becomes a glorified editor, a judge of quality rather than a creator of content. The energy savings alone could be the difference between AI being a climate catastrophe or a sustainable tool.
What This Actually Means
It means that the era of 'bigger is better' might be giving way to 'smarter is faster.' If software like vLLM can effectively mask hardware deficiencies, then the pressure on chip manufacturers shifts. They don't need to build the perfect chip; they need to build the chip that handles these speculative bursts most gracefully. This 'software-defined performance' is a massive win for open-source ecosystems because it allows us to squeeze juice out of hardware that was previously considered 'second-tier.'
Ultimately, speculative decoding is a confession that we've hit a wall with traditional compute. We can't move electrons much faster, so we're moving them smarter. It’s a beautiful, messy, probabilistic workaround for the rigid limits of physics. I’m left thinking about what other parts of computing we can 'guess' our way through. If we can do it with text, why not with video frames, or weather simulations, or drug discovery? We are entering the age of the informed shortcut.
Quick Answers
Does speculative decoding change the quality of the AI's answer?
No, because the larger 'parent' model still has to verify every single token; if the guess is wrong, it's corrected instantly, ensuring the output remains identical to what the big model would have produced alone.
Why does this help AMD specifically?
It helps any hardware that isn't the 'default' by shifting the performance burden away from proprietary hardware optimizations and into open-source software kernels that can be tuned for any chip.
Is there a downside to this technique?
It requires more VRAM to hold two models at once (the big one and the draft one), and if the draft model is poorly matched to the big one, you actually waste power on bad guesses.


